 FilePreserve
Why FilePreserve exists
The idea came out of hitting the same wall over and over: once a file had been archived by a separate vendor, the merge tool simply couldn't see it anymore. Someone had to log into that vendor's own console, manually restore the file, and only then try the merge again — one file at a time, usually mid-audit, under time pressure.
Every archive vendor in this category — including the well-funded, multi-year ones — sells archiving and retrieval as two separate tools that were never designed to talk to each other. That looks less like a deliberate choice than a blind spot: built for general storage cost-cutting, without much thought for the teams who actually get audited and need those files back, fast, in one piece. FilePreserve is built to close that specific gap by being both halves of the workflow at once: the archive engine and the merge/export tool, as one system.
It's built for the two buyer segments that feel this pain the most directly and on a documented, dated timeline: device/pharma quality teams managing FDA CAPA and complaint records, and health plan teams running CMS RADV audit response. See CAPA & complaint teams and RADV audit response for the specifics.
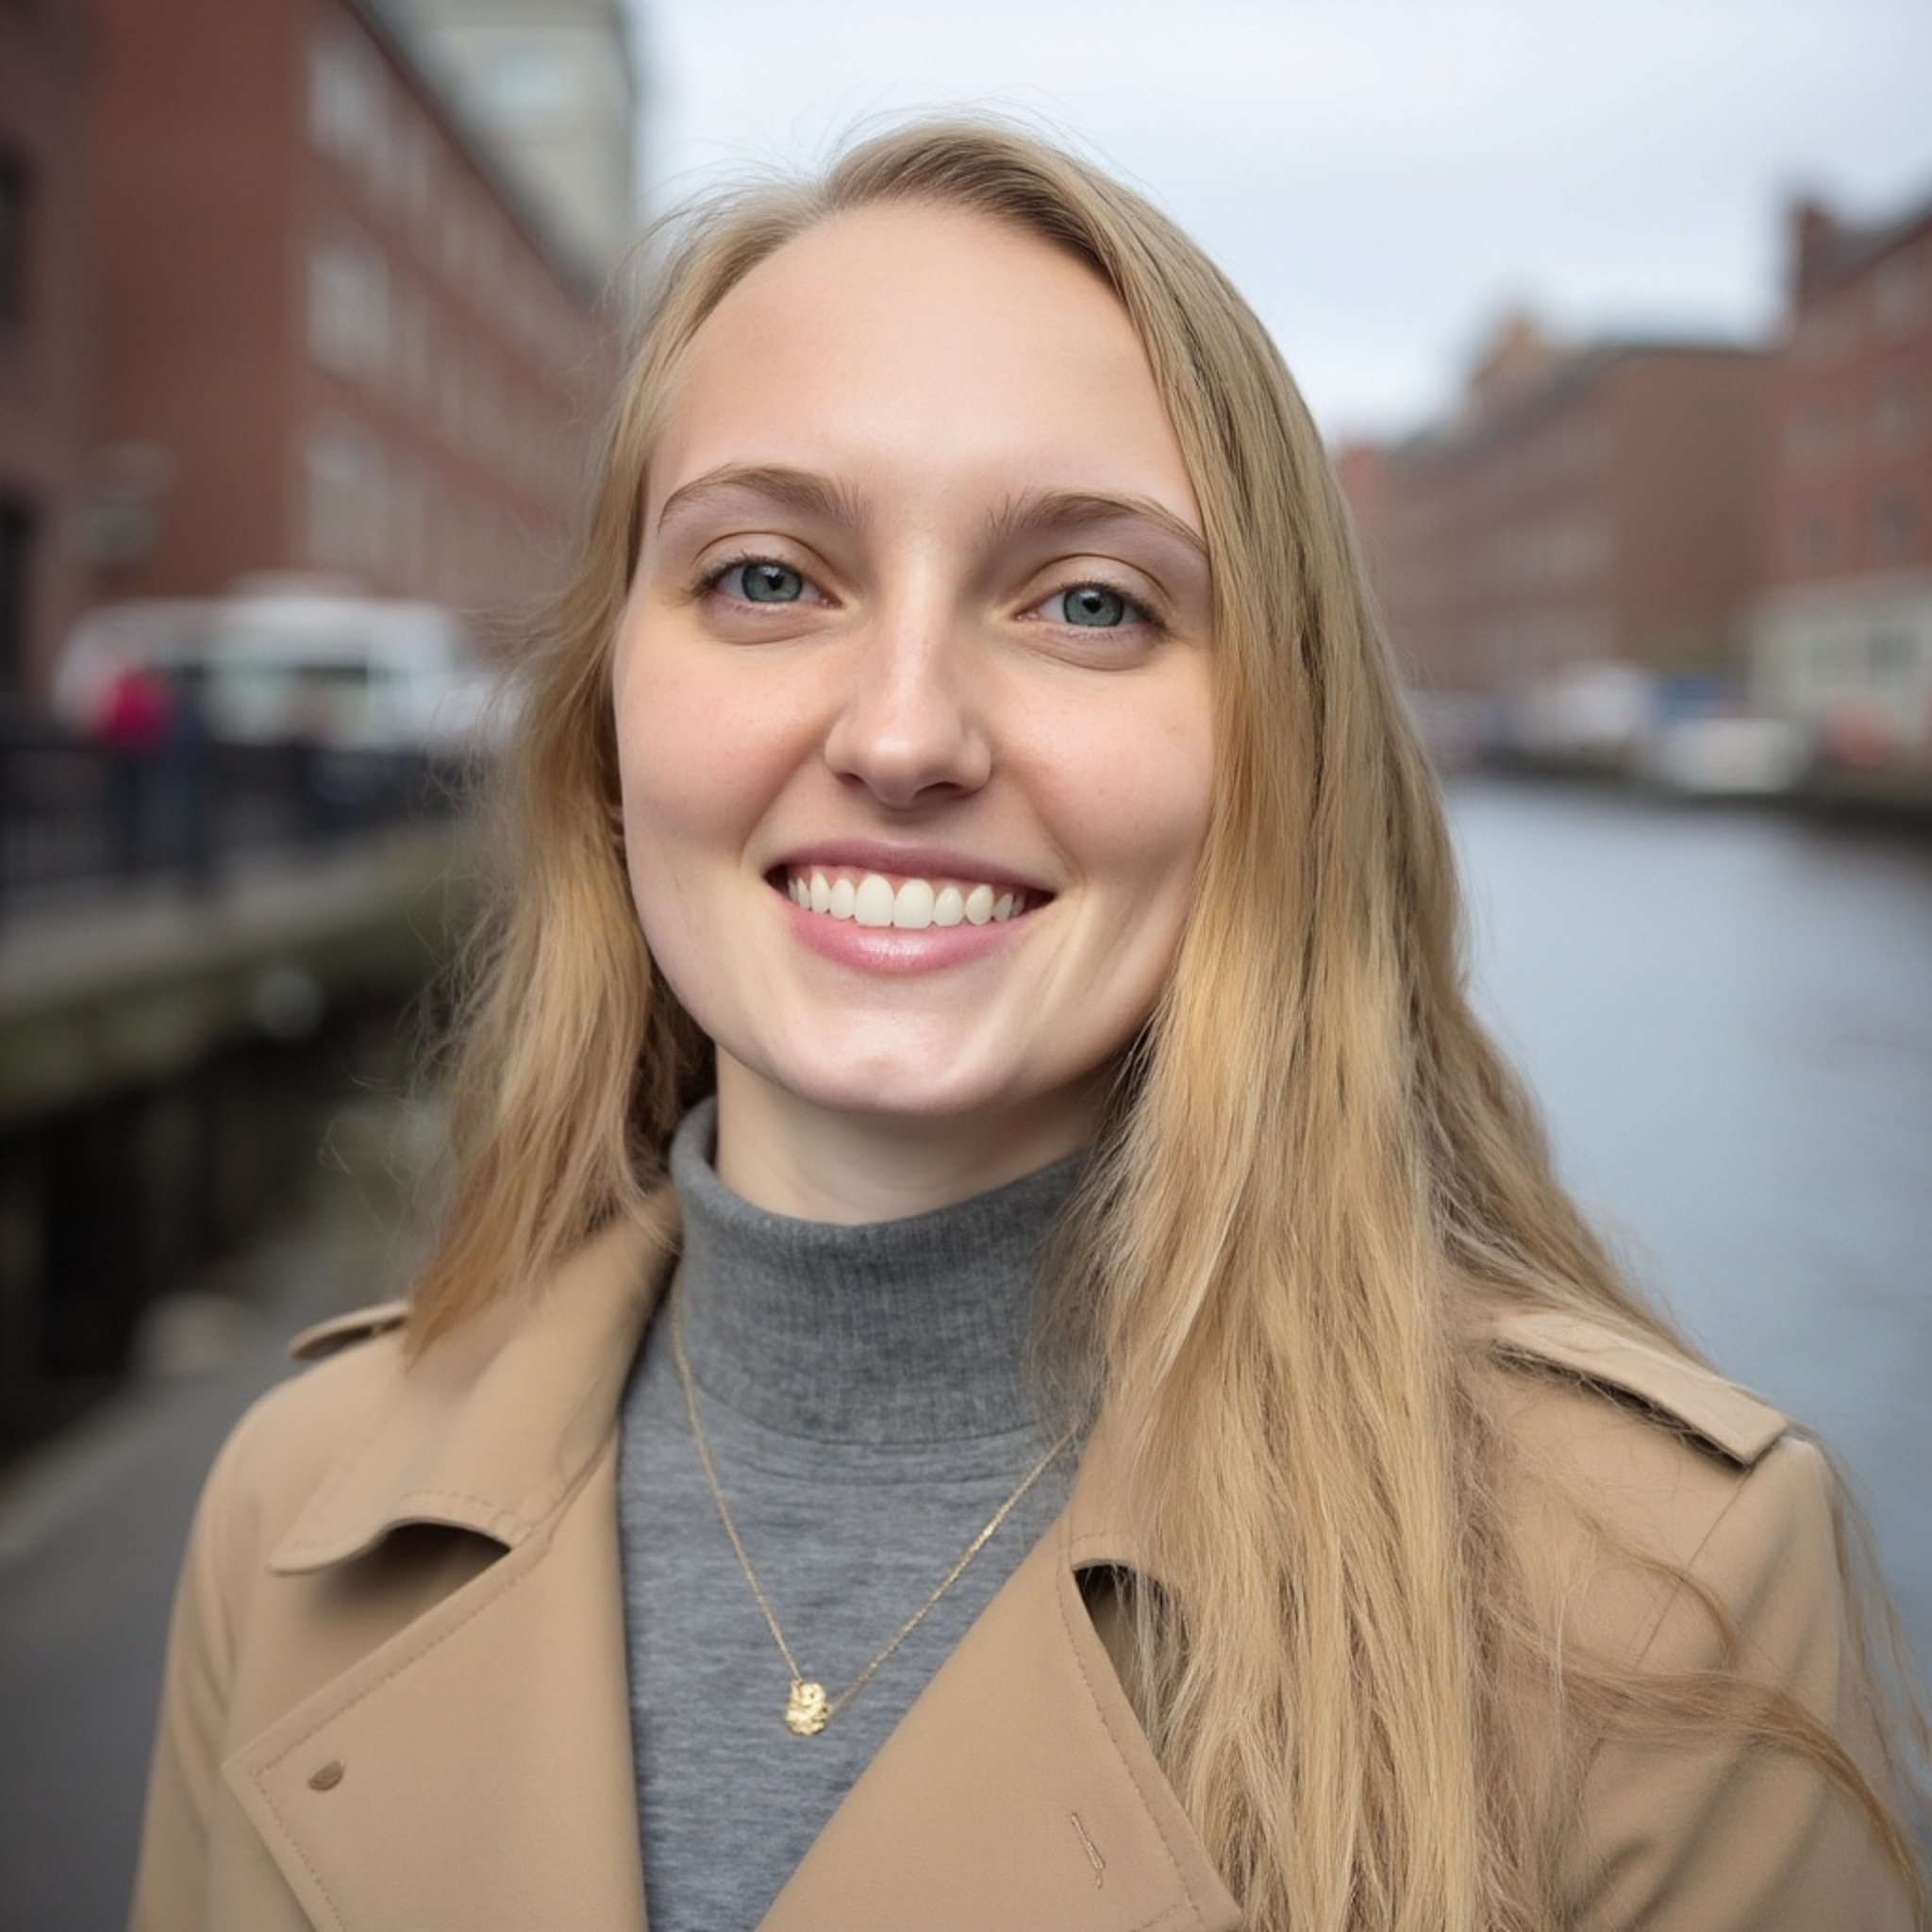
Georgina Hawley
Builder and operator of FilePreserve — solo, end to end: product, code, and support. In Salesforce since 2020, across admin, consulting, product, and architecture roles — now a Salesforce Certified Application Architect, one of the platform's two most senior architect-track credentials, with 14 active certifications in total. Day to day, that includes hands-on work inside a regulated, audited organization under HIPAA and SOC 2 — the same kind of compliance pressure FilePreserve is built for.
Reachable directly, not through a support queue: hello@filepreserve.com
A solo operation, on purpose — not a limitation to apologize for.
Support, honestly scoped
Email support is answered by the same person who builds the product, typically within 1–2 business days — not a ticket queue, and not a 24/7 SLA. That tradeoff is stated plainly in the Terms, not buried.
Architecture that limits the blast radius
Your Salesforce data never leaves your org, and archived files live in an AWS S3 bucket you own — never FilePreserve's own infrastructure. See Security for the full reasoning. That's a deliberate design choice suited to a small, independent operator, not an afterthought.
No inflated team, no invented case studies
What you read on this site is what's real: one builder, one product, real documented features, real pricing set against real published comps. Nothing here is staged.
What exists today, and what does not yet
FilePreserve is a Salesforce managed package. It has been built and tested against a live Salesforce org, covering archiving, retention, legal hold and the related-record file merge with automatic retrieval of archived files. It is not yet listed on AppExchange, and joining the waitlist is the way to get early access.
It is not SOC 2, HIPAA or otherwise compliance-certified, Amazon S3 is the only storage backend that has been tested, and there are no customer case studies or reviews here because the product is not yet publicly available. The plain-language guides and the detailed how it works page describe exactly what the product does and where its limits are.
Have a question this page didn't answer?
Most answers are already written down — check there first. If not, reach out directly: no sales team, no runaround.